Get the next story in your inbox
How businesses use AI without exposing data, and who stays in charge of it. Every Monday.
Pasting data into AI. Is it safe?
Human in Charge is a weekly newsletter about how businesses actually use AI and who stays in control. This is the second one, on using AI without exposing data.
Is there a security issue with copying and pasting data into ChatGPT? Am I exposing confidential information unknowingly? And is there any way to use AI without exposing data at all?
Joe works for a large drinks manufacturer. He has one task this quarter that’s easy to say, but hard to do, finding out why sales fell in one region and not another.
From his records, he can immediately see the shipments, their own pricing and the reports shared through his supplier portal. However, after a while he realises that based on this, he won’t be able to understand why sales fell in this specific region as nothing is out of the ordinary.
This means that the issue must be at the stores selling their product in the region.
He proceeds to immediately contact the stores and ask for records on when and what was sold from their products, what was next to their product on the shelf and at what price, or if they had a promotion or not.
But when the store looks into the data they realise they can’t provide this. This would aid Joe’s company against the competition, putting them in a difficult legal position.
Passing around sensitive data is exactly the kind of thing competition regulators aim to stop.
An industry grew in that gap. “Typically there are third-party analytics companies that sit in between,” Rami Akeela says. “They collect data from both retailers and manufacturers.”
It works, but everyone involved is holding someone else’s most sensitive numbers, so before anything moves there are lawyers, weeks of negotiation, and a contract setting out which fields may be looked at and by whom.
The wall Joe hit is the same wall that stands between every company and the AI it would like to use. Your customer’s data is too valuable to expose. Not to a competitor, not to a supplier, and not to a model you signed up for last Tuesday.
The moment of doubt
If you have complex spreadsheets with endless numbers and are trying to find ways to present it to your superiors, what do you do?
You copy and paste it into ChatGPT or Claude, maybe Gemini, and leave a prompt with what you need to show to your superiors. But after a while, you may start to think, is this safe? I registered to ChatGPT and now I am putting in the data of our company. Is this secure? If this gets out, what will your customers think?
Could the company be fined, and will you be fired from your job for this mistake?
Is there a way to securely use AI, without needing to worry about these issues?
This is where confidential AI systems come into play.
Meet Rami Akeela, PhD, founder of Nera Systems
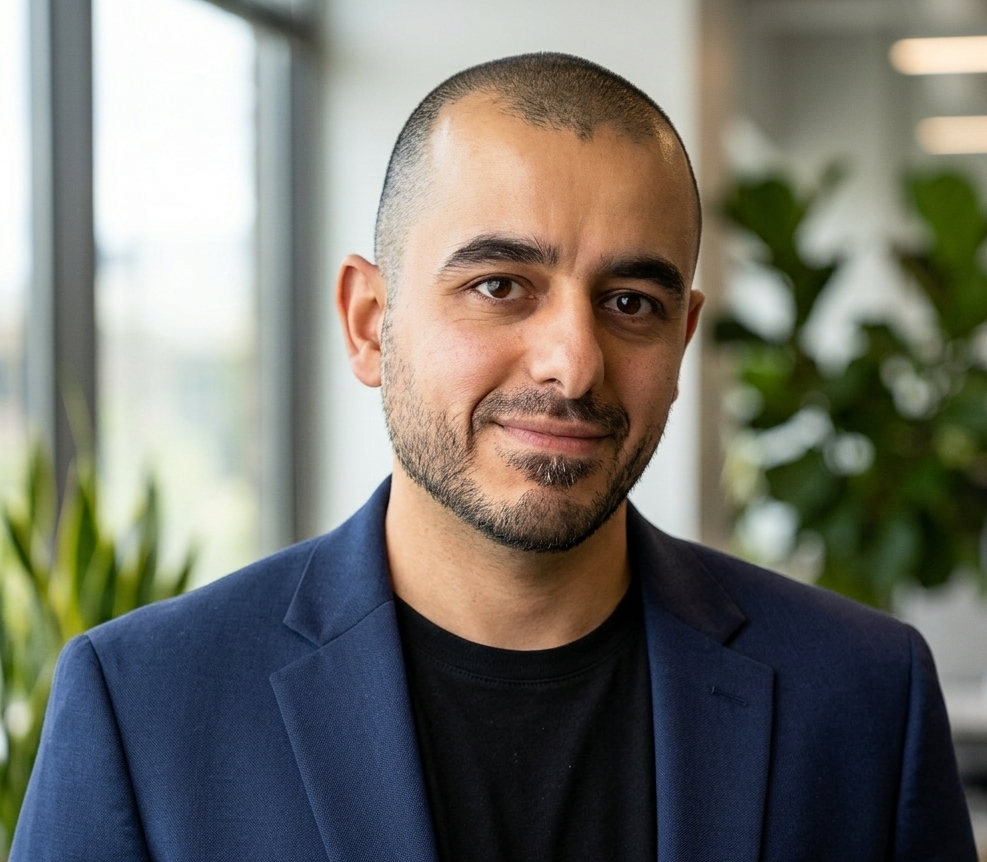
Rami spent twenty years building things most people never see. Hardware and software designed together, communication systems, IoT, then machine learning. In 2019 he moved into cryptography, specifically zero-knowledge proofs.
He was early enough that his work on it is peer-reviewed and citable, and he did not stay in the lab.
“I founded the very first company to build an end-to-end proving system that is FPGA accelerated as well, because the software was extremely slow.”
FPGAs are chips you can rewire for the job at hand, and they were his way of making the cryptography fast enough to actually deploy. It worked well enough that Intel and AMD came on as technology partners of that company, because he was opening a market they were not in. He went on to co-organise Z-Prize, the competition to make this work even faster.
Rami doesn’t come from compliance. He’s an engineer who thinks the industry is arguing about the wrong layer.
From zero-knowledge proofs to AI
When AI came about with the boom of ChatGPT and LLMs, he saw the same problem he had watched play out in crypto years before.
“I could see that it will actually face the same exact issue that blockchain has faced years before, which was data exposure… but we know the answer to this. There are technologies that we can actually use today to protect data as we use AI.”
Why should we worry about giving confidential client data to ChatGPT? Is it not possible to get ChatGPT into a secured area, where it can do our tasks while we enjoy the benefits?
“When it comes to security, what really needs to happen is that instead of coming up with solutions that address the issue after the fact, we need to fix it before it happens.”
Secure by design. A way of designing that aims to “prioritize the security of customers as a core business requirement, rather than merely treating it as a technical feature”, as CISA puts it.
He founded Nera Systems in 2023 to build it. His answer to how you use AI without exposing data is simple in the outline, the file is encrypted on your own machine, before anything leaves it. Only the encrypted version goes to the model. The answer comes back, and only your screen shows it in the clear. Not Nera, not Google, not Anthropic.
The wrong layer
Ask most companies what they are doing about AI risk and you will hear about policies, protocols, another doc hidden somewhere. Who is allowed to use which tool. What may be pasted where. A register of approved software, a sign-off process, a training session everyone clicks through.
This is a necessary step. It should not be the only one.
“Security and privacy are two different things. Sometimes we use them interchangeably, but really they’re different. A lot of the discussion today, and the effort that is happening, is conflating these different terms and addressing these issues with the wrong tooling, or at the wrong layer.”
So governance is the rules about who may look at something. Access control is the lock on the door. Both assume the same thing, that the data is sitting there, readable, and the only question left is who gets the key.
“I would say 99% of companies and organisations are talking about governance. And governance is important, but governance is one layer. We always wanted and needed governance. AI governance needs to be well defined. It’s not, it’s in the early days. But we still need governance. We still need access control. What we’re solving is the layer below them, which is data exposure. And we’re eliminating that by design.”
He is not saying policies are pointless. He is saying they are the second question, and the industry is skipping the first one.
Guardrails come too late
The clearest example is the one everybody is currently building, AI agents. They go off and act in our stead, fenced in by rules about what they may and may not do.
“When we talk about AI agents, what people talk about is guardrails. Sure. But we only realise that something went wrong after it had already gone wrong, and it went rogue. That’s the news that you read about, AI agents doing things nobody intended. That’s because it was not well contained and well defined from the very beginning.”
“But if it doesn’t even have the ability from the very beginning, if the agent doesn’t even see the data, even if it does go wrong, what happens? It doesn’t even see the data.”
In other words, you can write a rule saying the model must not leak the client list, and then spend your life checking whether it did. Or the model can never receive the client list in the first place, and the question stops existing.
“That makes the job of the governance layer and the access control tooling a lot easier to manage and to define.”
Which is a polite way of saying the paperwork gets easier when there is less to be frightened of.
So how do you use AI without exposing data?
Containing it.
But not everyone is a security engineer, and we are all already used to pasting text or images into Gemini.
“What do you use today already? People use ChatGPT. People use Claude. People use Gemini already, from their browser or from their phones. Can we make that same user experience, but now confidentially and securely?”
In short, that is the core of Nera. Their clients continue working as they have been before, but now without leaking client data and risking the consequences of exposure.
“CPG is where we started, but the problem is sharpest in regulated finance. Banks, credit unions and insurers are under real pressure to use AI, and their staff are already pasting customer data into chatbots whether they’re allowed to or not. Those are the teams we’re focused on now.”
Back to Joe
Remember Joe, and the wall he hit trying to find out why sales fell in one region.
That wall is where Nera started.
“Our first wave of customers were from CPG, consumer packaged goods.”
The manufacturers, the retailers, and the analytics firms sitting between them holding everybody’s most sensitive numbers. The arrangement worked, it cost weeks of negotiation every time, and what came out the other end was deliberately partial. Rami’s name for the part nobody is allowed to look at is the best phrase in the whole conversation.
“You still end up with something called dark data. You’re saying, okay, you can use this data, but this you cannot see. So you actually lose the value of this data, because it needs to stay protected because it’s too sensitive.”
His first customer was egglife, a CPG brand.
“What we did was deploy our solution to securely protect all data from different vendors and run the analytics on it while it was all encrypted, and still get the results. It made the process a lot easier and the timeline a lot shorter, because now they don’t have to go back and forth on looking at it.”
They used AI without exposing data, so nobody had to agree who was allowed to look. The question Joe’s contact could not answer stopped being a question.
The part nobody can answer for him
One thing he told me in writing that most founders would have left out. It is the question this piece ends on.
“Whether an architectural approach, preventing exposure by design rather than governing access to it after the fact, is even legible to current regulatory frameworks. Most existing taxonomy assumes the AI already has the data and asks who’s allowed to look. We don’t have a clean answer for where ‘the model structurally can’t see it’ fits in that model yet.”
Every rule written so far assumes the model can see your data, and asks who gave it permission. He built something where that question does not apply, and nobody can tell him which box it belongs in.
What he didn’t see coming
At the end of our interview, I asked him what he wished he had known when he started.
“Man, that’s a good question. I think, and everybody would say the same thing… it’s a lot bigger than what I thought it was going to be. The problem itself, I mean.”
“I consider myself to be lucky to have seen this play out years before it actually started becoming visible to the rest of the world. But that still doesn’t mean that I realised how massive a problem this is going to be.”
For all that, he is not pessimistic, and in a batch of interviews where most people are, that stands out.
“That still doesn’t change anything for me, because it only means that there’s a bigger opportunity here.”
Rami is arguing about the layer we build on. Art50 records who reviewed what and stands behind it, which is the paperwork layer he says the industry is too focused on. He has a point. Removing exposure and recording accountability are different jobs. You can use AI without exposing data, and still not know who approved what went out. Both need answering.
Rami Akeela, PhD, is founder and CEO of Nera Systems. He writes a newsletter on confidential AI called In Confidence.
Get the next story in your inbox
Businesses using AI, and the people who stay in charge of it. Every Monday.
Keep a record of your own AI work. Log that a person checked it, and get a proof link anyone can verify.
Get access →